
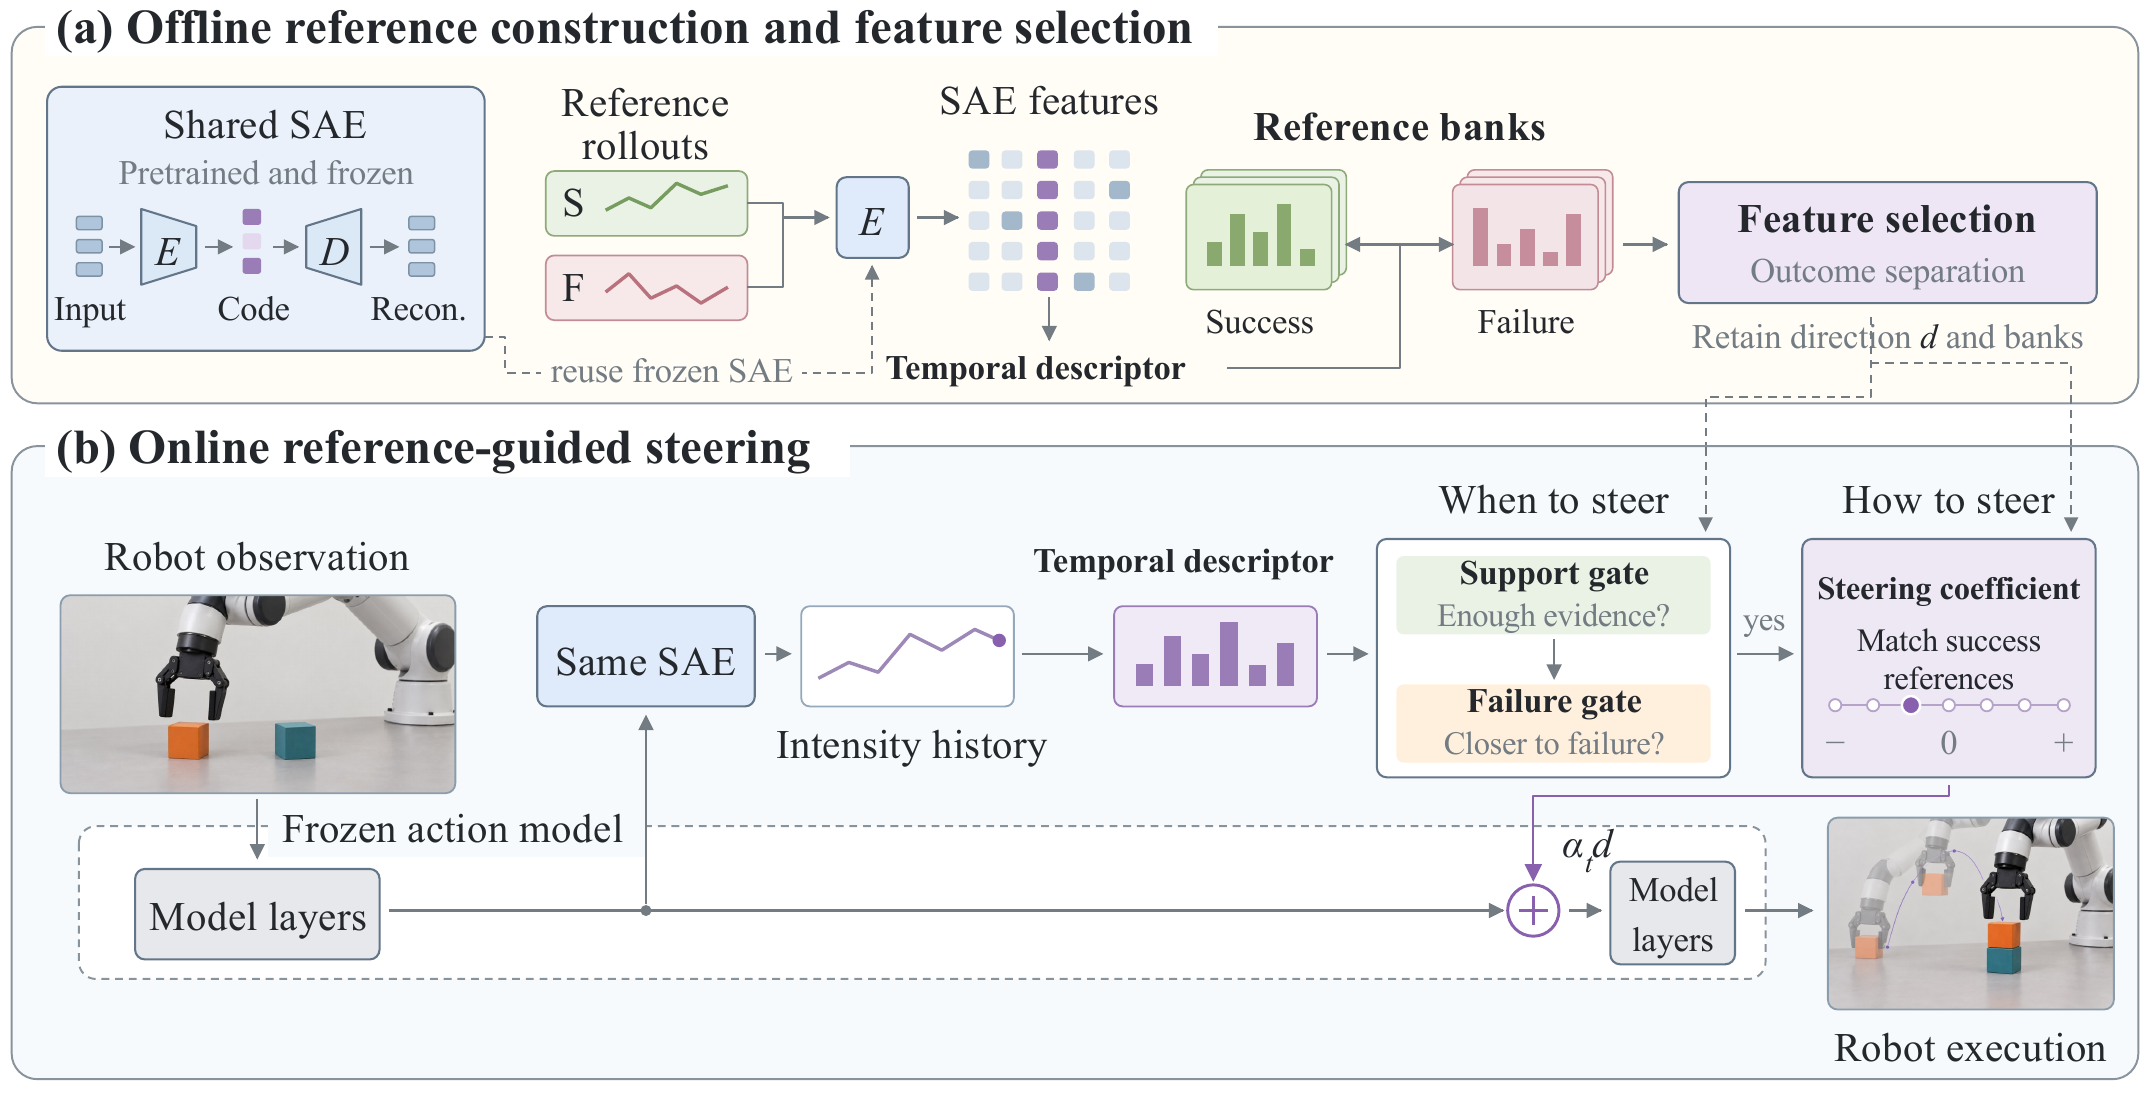
One temporal descriptor connects feature selection and online steering.



Kaichen Zhou1,2,*, Zhiyan Li2,*, Chongkai Gao3, Yuhan Wang4,
Wenlong Huang3, Maggie Wang3, Fangneng Zhan1, Manling Li5,
Qianqian Wang2, Mac Schwager3, Zhuang Liu6,
Li Fei-Fei3, Mengyu Wang2,†, Paul Pu Liang1,†
1 MIT 2 Harvard University 3 Stanford University
4 Imperial College London 5 Northwestern University 6 Princeton University
* Equal contribution † Equal supervision
Overview · Quick Start · Configuration · Workflow · Release Scope · Citation
Can a few successful and failed trials tell a frozen robot action model what to change—and when?
SteerAct uses a pretrained sparse autoencoder (SAE) to expose internal features and their steering directions. A shared temporal descriptor summarizes how each feature's activity rises, falls, or fluctuates, allowing comparisons across rollouts without aligning individual timesteps.
- Before steering — select what to change. Use successful and failed reference rollouts to rank features by outcome separation and construct task-specific reference banks.
- During execution — decide when to intervene. Compare the observed feature history with these banks. Intervene only when the history has sufficient reference support and resembles failure.
- When intervention is enabled — choose a signed correction. Search a bounded set of coefficients for an edit that moves the predicted descriptor closer to successful references. Keep the action model and SAE frozen.
The paper studies single-feature steering using 24 outcome-labeled reference rollouts per task, across VLA and WAM backbones. See the project page for the paper's broader evaluation and robot videos.
Current code scope. This folder provides collection, SAE training, feature ranking, and steering evaluation for π₀.₅ and Fast-WAM on nine RoboTwin 2.0 tasks. It requires external simulator/model integrations and checkpoints; it is not a self-contained reproduction of every paper experiment. See Release Scope.
Single-feature setting. The supplied recipes currently set
steering.top_kto 4. To use the paper's single-feature formulation, set it to 1 before runningrankandinfer. This is separate fromsae.top_k = 100, which controls SAE sparsity. No configuration files are changed by this README.
Use the Linux/CUDA environment for your selected RoboTwin model integration. Install its simulator assets, model dependencies, and compatible source checkouts first. The exact integration files required by this package are listed under External integrations.
The Python package requires Python ≥ 3.10, NumPy ≥ 1.24, PyTorch ≥ 2.1, and huggingface_hub ≥ 0.20. Once these are available in the model environment, install this package without changing that environment's dependency versions:
cd /path/to/SteerAct
python -m pip install -e . --no-deps
python -m steeract --help
--no-deps assumes the declared dependencies are already installed; it does not install the simulator or either action model. Collection and policy inference require CUDA as currently implemented. --device cpu can be used for offline SAE training/ranking, but does not move the robot policy to CPU.
For the shared-SAE setup, start with an all_tasks recipe:
STEERACT_CONFIG=configs/pi05_all_tasks.json
# For Fast-WAM instead:
# STEERACT_CONFIG=configs/fastwam_all_tasks.json
Before proceeding, edit the selected JSON file:
- Replace the checkpoint and normalization/statistics placeholders with your actual assets.
- Set the RoboTwin checkout path, and the Fast-WAM checkout path if applicable.
- Choose a fresh
paths.run_dirfor generated artifacts. - Set
steering.top_kto1for the paper's single-feature setting.
All local paths are resolved relative to the JSON file, not the shell's working directory. Absolute paths are recommended. See Configuration for required fields.
Inspect the resolved recipe:
python -m steeract collect --config "$STEERACT_CONFIG" --dry-runA dry run checks configuration structure only. It does not verify that checkpoints, simulator assets, dependencies, or external adapters exist.
Run these commands from the repository root in the prepared model environment:
# Collect outcome-labeled rollouts and hidden activations.
CUDA_VISIBLE_DEVICES=0 python -m steeract collect --config "$STEERACT_CONFIG"

# Train the SAE on the collected activations.
CUDA_VISIBLE_DEVICES=0 python -m steeract train --config "$STEERACT_CONFIG" --device cuda:0

# Select steering features and construct task-specific reference banks.
CUDA_VISIBLE_DEVICES=0 python -m steeract rank --config "$STEERACT_CONFIG" --device cuda:0

# Evaluate the frozen action model with online steering.
CUDA_VISIBLE_DEVICES=0 python -m steeract infer --config "$STEERACT_CONFIG" --device cuda:0
The same sequence supports all four supplied recipes. For a smaller initial run, choose a single_task recipe; it trains a task-specific SAE rather than the shared SAE used by the all_tasks setup.
| Recipe | Backbone | SAE training data |
|---|---|---|
pi05_all_tasks.json |
π₀.₅ | Shared across 9 tasks; 24 reference rollouts/task |
fastwam_all_tasks.json |
Fast-WAM | Shared across 9 tasks; 24 reference rollouts/task |
pi05_single_task.json |
π₀.₅ | One task; 24 reference rollouts |
fastwam_single_task.json |
Fast-WAM | One task; 24 reference rollouts |
all_tasks pools 216 reference rollouts to train one SAE at the selected layer for the selected backbone. Feature selection and reference banks remain task-specific. The current loader accepts exactly one registered task or all nine, not arbitrary task subsets.
| Configuration field | Required input |
|---|---|
paths.run_dir |
Output directory for this experiment |
paths.robotwin |
Compatible RoboTwin checkout, including the integration files below |
paths.checkpoint |
Task/model checkpoint compatible with the selected policy configuration |
paths.norm — π₀.₅ |
Normalization asset directory for that checkpoint/dataset |
paths.fastwam — Fast-WAM |
Compatible Fast-WAM source checkout |
paths.stats — Fast-WAM |
Dataset statistics JSON for that checkpoint |
paths.dit, paths.vae, paths.text_encoder, paths.tokenizer — Fast-WAM |
Local model assets or the supplied hf:// references |
Fast-WAM's hf:// entries are resolved through Hugging Face Hub and may download large model assets. They do not supply the task checkpoint or dataset statistics. Checkpoint architecture, policy.config_name where applicable, embodiment, and normalization/statistics must agree.
Collection layers and intervention site
| Backbone | Required visual layers | Optional action-expert layers | Default SAE/steering layer |
|---|---|---|---|
| π₀.₅ | paligemma_L15, paligemma_L16, paligemma_L17 |
expert_L0–expert_L17 |
paligemma_L17 |
| Fast-WAM | fastwam_video_L27, fastwam_video_L28, fastwam_video_L29 |
fastwam_action_L0–fastwam_action_L29 |
fastwam_video_L29 |
The supplied recipes collect all listed layers: 21 for π₀.₅ and 33 for Fast-WAM, saving up to 256 tokens per layer per decision. To reduce collection storage, keep all three required visual layers and omit any unneeded action-expert layers from collection.layers. Action-expert collection uses the first denoising call at each decision.
Action-expert collection is not action-expert steering. The public configuration loader currently restricts SAE training and steering to one of the three visual layers. The paper's Dec intervention setting is not exposed by these recipes.
Changing the layer or collection recipe changes the artifact identity; use a fresh run directory and recollect rather than mixing incompatible manifests.
Registered RoboTwin tasks
put_bottles_dustbin
stack_blocks_three
blocks_ranking_size
place_dual_shoes
dump_bin_bigbin
open_microwave
turn_switch
place_mouse_pad
pick_diverse_bottles
| Stage | What it does | Main output |
|---|---|---|
collect |
Runs the frozen policy and records outcome-labeled activation histories | Activation shards and manifest |
train |
Fits a TopK SAE at the selected hidden layer | SAE checkpoint |
rank |
Compares success/failure temporal descriptors, selects features, and builds references | Rankings and steering bank |
infer |
Applies gated, signed corrections during held-out robot rollouts | Success summaries and controller traces |
Each reference rollout must contain at least five decisions, so both triple spacings can be represented. Each task must provide at least two successful and two failed rollouts for feature ranking. Collection does not balance outcomes automatically: 24 collected rollouts alone do not guarantee a usable split. Inspect the collected outcomes before training/ranking; use a new collection recipe/run if the split is insufficient.
The SAE defaults are a dictionary of size 8 × hidden dimension, TopK sparsity k = 100 (at most 100 nonzero entries per token), 15,000 training steps, batch size 1,024, and learning rate 3 × 10⁻⁴. The SAE is then frozen for feature selection and steering; the pretrained action model is not fine-tuned by any of these four stages.
Each feature history is summarized by an 18-dimensional descriptor: for each of two spacings, six local order-pattern frequencies, normalized entropy, tie frequency, and an availability indicator. Reference-bank separation identifies candidate steering features.
During execution, the Support Gate checks whether the history provides sufficient evidence for comparison, and the Failure Gate checks whether it is closer to failed references. When both gates are open, a bounded search chooses a signed coefficient using predicted improvement toward the success bank. The controller re-encodes the edited activations and records the measured result for the next decision.
For steering.top_k > 1, the implementation averages selected features' intensity histories and decoder directions, then uses one aggregate bank and one coefficient. It does not run independent controllers for each feature.
Default controller settings
Set overrides under steering.controller; an empty object uses the defaults in steeract/method.py.
| Setting | Default |
|---|---|
posterior_samples |
500 Dirichlet draws |
support_mass |
0.65 |
support_k / support_quantile |
3 / 0.95; support radius is 3 × this reference-distance quantile |
outcome_k |
3, capped by the smaller bank |
min_windows |
3 observed triples at each spacing |
support_open / support_close |
1 passing / 2 failing checks |
failure_open / failure_close |
2 passing / 2 failing checks |
alpha_max / alpha_step |
10 / 0.5; 41 candidates from −10 to +10 |
min_effective_gain |
0.001 |
Support comparisons use raw descriptor distances; outcome comparisons and coefficient scoring use fixed, class-balanced coordinate scales. The zero edit remains the fallback when no tested correction strictly improves the objective.
- Held-out seeds: recipes use 24 reference episodes/task starting at seed 0 and 200 evaluation episodes/task starting at seed 5000. Collection and evaluation seed ranges must not overlap.
- Step limits:
evaluation.max_steps_multiplierdefaults to 2. Match evaluation horizons and budgets when comparing against unsteered policies or external baselines. - Recipe changes: changing the backbone, tasks, selected layer, collection settings, policy settings, or source-asset paths changes the collection identity. Use a fresh run directory and regenerate compatible artifacts.
- Steering changes: after changing
steering.top_kor controller settings, rerunrankbeforeinfer. Existing evaluation directories reject incompatible configurations. For new controller/evaluation settings at the same feature count, archive or rename the existingresults/top<k>/directory before rerunning; keep the compatible SAE and bank in place. Changingrun_diralone does not move those inputs. - Collection errors: invalid/too-short episodes and backend exceptions are logged and raised.
max_attemptsis not an automatic recovery mechanism for these errors.
Generated artifacts are written under paths.run_dir:
<run_dir>/
├── activations/
│   ├── manifest.json            # Recipe identity and collected episodes
│   └── ...                      # Per-task, per-episode activation shards
├── sae/
│   ├── model.pt                 # Frozen SAE used by rank and infer
│   └── training.json
├── ranking/
│   └── <task>.json              # Feature scores and selection
├── steering_bank.json           # Task-specific references and controller settings
└── results/
    └── top<k>/                  # top1 for single-feature steering; supplied default: top4
        ├── configuration.json
        ├── episodes.jsonl
        ├── summary.json
        └── traces/
Success rates in summary.json are stored as fractions in [0, 1]; multiply by 100 for percentages. The macro-average weights each evaluated task equally.
| Component | Status in this folder |
|---|---|
| Activation collection, TopK SAE training, feature ranking, online controller | Included in steeract/ |
| π₀.₅ / Fast-WAM adapters for the nine registered RoboTwin tasks | Included; require compatible external integrations |
| Shared-SAE and single-task-SAE recipes | Included |
| Simulator assets, task-policy checkpoints, normalization/statistics | External; not bundled |
| Collected activations, trained SAEs, and reference banks | Generated by the workflow; no pretrained artifacts bundled |
| DexJoCo and real-robot runners | Not included in this folder |
| Action-expert steering and DSRL/COAST/DrVLA baseline runners | Not exposed by the current four-stage CLI |
| Pinned external source revisions, environment lockfile, automated test suite, license file | Not included |
The backend adapters expect the following specific source layout. A generic RoboTwin installation is not sufficient unless it includes these integrations:
<paths.robotwin>/
├── scripts/eval_policy_xpolicylab.py          # Both backbones
├── description/task_instruction/<task>.json  # π₀.₅ task instructions
└── XPolicyLab/                              # π₀.₅
    ├── policy/Pi_05/model.py
    ├── policy/Pi_05/openpi/src/
    └── utils/process_data.py

<paths.fastwam>/                             # Fast-WAM
├── experiments/robotwin/fastwam_policy/deploy_policy.py
└── configs/sim_robotwin.yaml
The π₀.₅ adapter expects 18 PaliGemma layers, 18 action-expert layers, and task-instruction JSON files containing full_description. The Fast-WAM adapter expects 30 video blocks, 30 action blocks, and the model.mot._apply_expert_post_block_tensor interception API. Exact compatible source revisions are not pinned in this folder; verify these interfaces before launching an experiment.
Use python -m steeract for the workflow documented here. The separate SAE/ directory contains legacy wrappers that depend on an external SAE/sae_pipeline checkout and use different defaults and artifact formats. Its checkpoints and banks should not be mixed with those produced by steeract/.
| File | Responsibility |
|---|---|
steeract/config.py |
Recipe validation, task registry, artifact identity |
steeract/data.py |
Activation collection |
steeract/sae.py |
TopK SAE and training |
steeract/ranking.py |
Feature scoring and reference-bank construction |
steeract/method.py |
Temporal descriptor, gates, bounded search, feedback |
steeract/inference.py |
Hidden-state intervention and evaluation |
steeract/backends/ |
π₀.₅ and Fast-WAM integration |
If you find SteerAct useful, please cite the paper.
@misc{zhou2026steeract,
  title   = {SteerAct: Unlocking Action Models through Few-Shot Temporal Steering},
  author  = {Kaichen Zhou and Zhiyan Li and Chongkai Gao and Yuhan Wang and
             Wenlong Huang and Maggie Wang and Fangneng Zhan and Manling Li and
             Qianqian Wang and Mac Schwager and Zhuang Liu and Li Fei-Fei and
             Mengyu Wang and Paul Pu Liang},
  year    = {2026},
  eprint  = {2610.25632},
  archivePrefix = {arXiv},
  primaryClass = {cs.RO},
  url     = {https://arxiv.org/abs/2610.25632}
}